Robert Lunt · Oct 23, 2026 · 12 min read
Why Enterprise Programmes Fail and How to Recover Delivery Grip
Most failing programmes do not need more governance, more people or another transformation framework. They need an honest diagnosis, hard commercial decisions and a small team capable of restoring delivery grip.
Whenever you sit across the desk from a board, a prospective client or an interview panel, one question tends to arrive early, and it is usually framed too narrowly.
How will you save us money on this delivery?
Cue the standard levers. Streamline ceremonies, offshore testing, optimise sprint velocity, then suggest a few weekends, as if exhausting a stretched team has ever repaired a broken delivery model.
If you want to save an enterprise seven or eight figures, the most commercially astute answer in the room may have nothing to do with tweaking Jira workflows or asking engineers to work another Saturday.
The real answer is asking the one question that terrifies every steering committee.
"Should we be doing this project at all?"
The best way to save ten, twenty or fifty million pounds is not to run an unviable project faster. Challenge the premise, test the hardest assumptions early and stop when the evidence no longer supports investment.
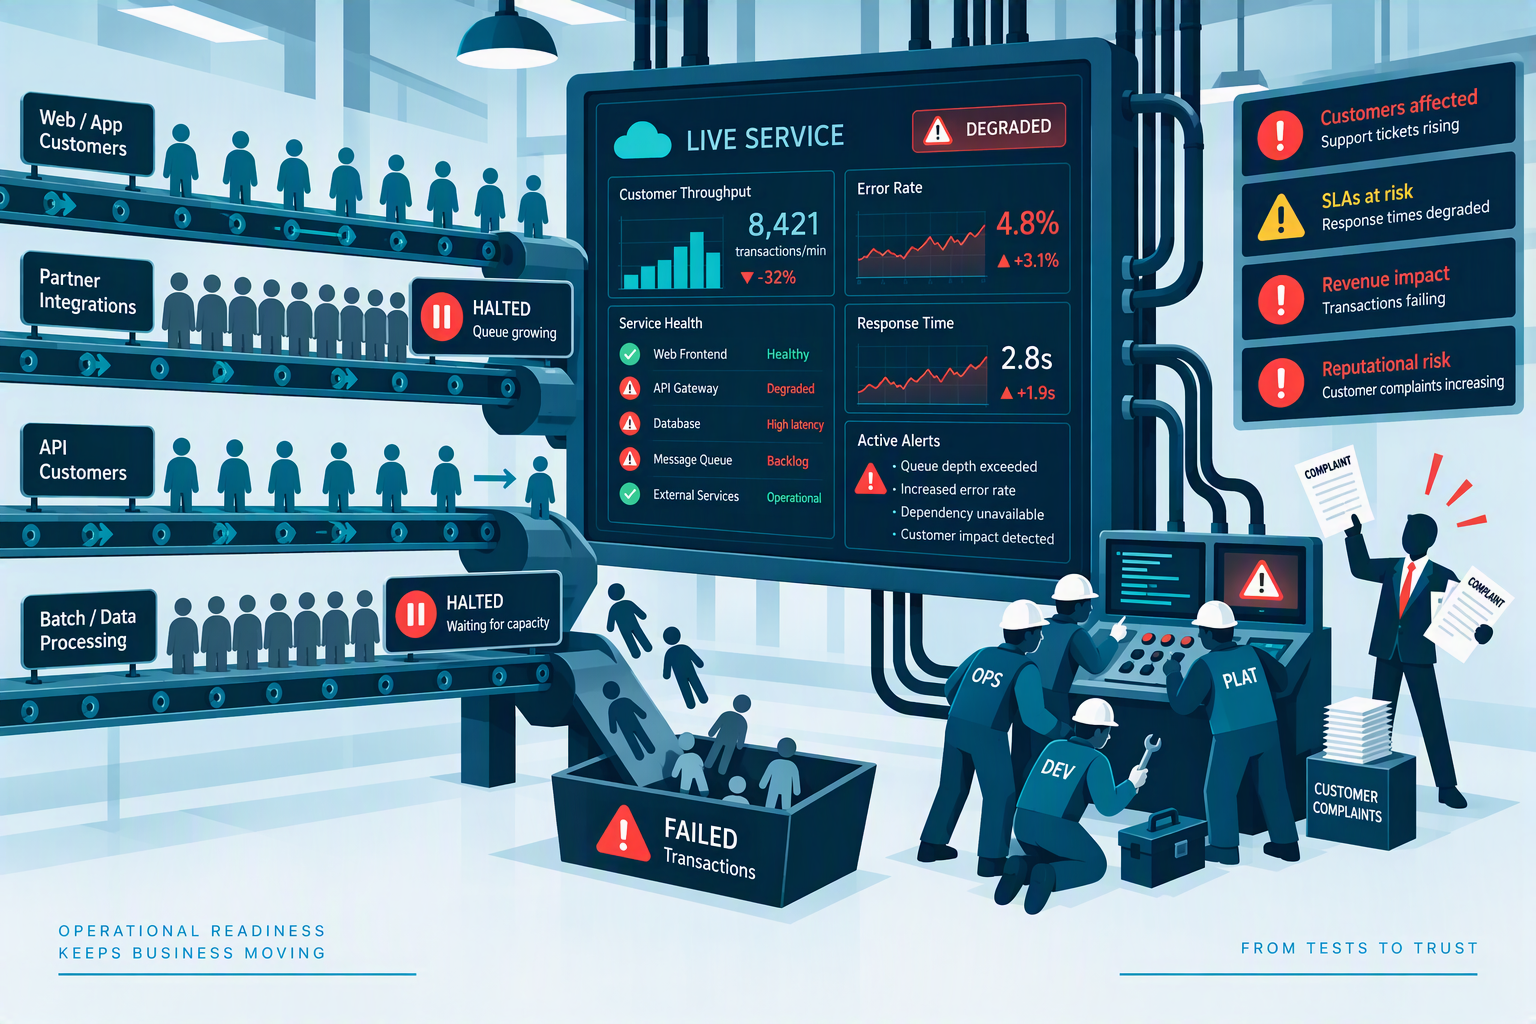
Yet nobody says it. Instead, the mandate gets signed, the budget gets committed and twelve months later the delivery has mutated into an expensive, ungovernable failure. The dashboards glow emerald green, the third-party suppliers have gone for a quiet walk along a short pier and the code base cannot survive contact with a live network.
How on earth did we get here? How do we actually fix the wreckage? And can this thing ever genuinely be delivered?
This is a guide to recognising when delivery has changed direction, and acting while a reset is still possible. Test the premise before mobilisation, expose integration and regulatory constraints before scale, judge progress through working software and align suppliers to outcomes. Without those disciplines, recovery becomes slower, more political and far more expensive.
1. The Programme Delivery Death March: Rituals Over Reality
Edward Yourdon coined Death March for initiatives whose scope, schedule, budget or staffing exceed reality by at least 50%. Everyone in delivery knows the programme is doomed, yet the corporate machine advances with a forced smile.
Instead, enterprise delivery simply modernised the rituals.
Agile did not kill the Death March. It gave it a reassuring rhythm. An unviable programme can now arrive in tidy two-week increments, with immaculate Jira hygiene. Stand-ups skirt the legacy core, planning turns weak architecture into colourful tickets and retrospectives recast systemic failure as a morale issue.
Enterprise culture is allergic to "No". A delivery lead who exposes an impossible constraint, missing API or fantasy business case is labelled cynical or uncollaborative. Cheerful certainty is rewarded instead.
Teams learn the survival rules. Agree to every request, mock the back end so Friday's demo sparkles and find a new job before integration. The monthly board still sees green dashboards while, below deck, the water reaches the engineers' necks.
2. Breaking the Delivery Lifecycle: Skipping "Should We?" and Redefining Shift Left
Every successful software delivery relies on an unbreakable three-part spine:
- Should We? (Discovery & Intent): Assessing real customer desirability, operational appetite and commercial viability before burning a single pound on engineering.
- Can We? (De-risking & Delivery Feasibility): Proving integration boundaries, technical viability, legacy dependencies and legislative constraints through working architectural spikes.
- Prove It (Delivery & Execution): Building, shipping and operating real, observable software through production pipelines to validate actual business value.
Enterprise programmes collapse because they routinely skip step one, wave away step two and charge headlong into step three on assumptions made of wet cardboard.
A Discovery that cannot stop a project is not a Discovery. Its job is to prove the project should not go ahead, and the ones that survive that scrutiny are the ones worth funding. Fail early, de-risk early, deliver value early. A Discovery should answer "Should we?" before anyone is allowed to answer "How quickly?".
The pattern is familiar. An executive sees a competitor or vendor deck. A mandate becomes holy writ. The business case is reverse-engineered. Eighty contractors start coding. "Should we?" disappears beneath "How quickly?"
The corporate graveyard contains well-documented examples of organisations that treated executive conviction as a substitute for validated demand, operational readiness and technical feasibility.
- FoxMeyer Drug: The $5 billion wholesaler committed more than $100 million to ERP and warehouse automation before proving volumes and dependencies. Load failures, inventory losses and bankruptcy followed, a lesson in testing scale and operations early.
- NHS NPfIT: National ambition never reconciled with the realities of disparate trusts. After nine years of conflict and difficulty, the programme was dismantled with a forecast cost of £9.8 billion and no single patient record.
- Quibi: Hollywood and Silicon Valley spent $1.75 billion on ten-minute mobile videos while restricting casting and screenshots, without proving anyone wanted the product. It closed six months after launch.
The industry reduced "Shift Left" to automated browser tests, AI-generated unit tests and a claim that quality was handled. Automating bad assumptions earlier does not save a project. It produces broken, unwanted nonsense faster.
True Shift Left is a delivery governance discipline. Validate desirability, feasibility, integration, security and operations before scale. A programme staffed only by people paid to salute is not a delivery team but an expensive chorus line on the Titanic. The best heroics happen before the contract ink dries.
3. The Silo Reality in Programme Delivery: Missiles, Grain and Fragility
Consultancies have spent thirty years selling "break down the silos", usually beneath slides of smiling cartoons holding hands across departments. It is snake oil. Silos are not accidents but survival mechanisms.
The missile silo houses InfoSec, Architecture, Data and Legal, hardened bunkers protecting assets and veto power. Approach without clearance and a procedural warhead can incinerate six months of roadmap.
The grain silo is engineering, a dry, dark store for specialised output, protected from bureaucratic weevils. The ladders come up, the music goes on and delivery accelerates in isolation.
Inside engineering, every impossible request receives a "Yes-Card". Mocks, hard-coded data and local environments keep tickets moving and executives smiling, until the output meets the enterprise.
- Compliance: Unencrypted personal data, missing audit trails and a cloud provider breaching sovereignty rules stop delivery.
- Architecture: Microservices choke on latency, queues back up and the legacy database locks.
- Operations: No telemetry, searchable logs, alerting or 03:00 runbook leaves support running for the hills.
The engineering silo felt safe right up until the moment reality arrived.
The answer is not to remove specialist boundaries but to make them testable. Before asking whether delivery is on plan, require evidence that five conditions hold. The business case remains valid, the hardest dependencies have been tested, a thin end-to-end transaction works in a shared environment, operational, security and regulatory constraints are embedded in delivery, and the supplier can demonstrate progress without relying on slideware or ticket counts. If two or more conditions are absent, the programme needs an independent reset, not another status meeting.
4. Delivery Smoke Signals: When the Instruments Start Lying
Programmes rarely fail without warning. They change direction first. Decisions slow, evidence softens, integration retreats, work in progress rises and reporting drifts away from software. By the missed go-live, the programme may have travelled wrongly for months.
The "Watermelon" Delivery
The dashboard stays emerald green because paperwork, not software, is complete. Four weeks before release, the polished PowerPoint watermelon splits open, red inside, and the PMO performs theatrical shock.
The Fiction of "90% Dev Complete"
"Dev Complete" often means untested, unintegrated and unverified, a happy path on a laptop against mocks, untouched by deployment, real data or external systems. Eighty per cent almost done is nothing done.
Governance Theatre as a Panic Response
Soon ten-person stand-ups host forty spectators, followed by a "sync on syncs". Leads update risks and colour spreadsheets while velocity measures how hard the hamsters spin, not whether the cage moves.
The Fraudulent Burndown Chart
The sprint-end plunge is not velocity but accounting. Acceptance criteria shrink and non-functional work is exiled to a technical-debt backlog so the points can be banked.
The Death of Flow and WIP Suffocation
Finally, flow collapses. Developers juggle four features, testers face thirty "Ready for Test" tickets and releases queue behind manual gates. Sixty-hour weeks look like momentum. The programme is stationary in deep mud with the engine overheating.
Each signal should trigger a specific response. Green reporting without integrated software requires an end-to-end demonstration. A growing Dev Complete queue requires a stricter definition of done. Expanding governance requires blocker removal and scope decisions. A sprint-end burndown collapse requires acceptance criteria and technical debt to be audited. Rising work in progress requires new work to stop until flow is restored. Warning signs only create value when they change behaviour.
5. Architectural Integrity: From Paper Design to Tested Constraints
Architecture fails at two extremes, pristine design that has never met reality, and "emergent" design with no shared intent. The workable middle is clear constraints, continuous validation and freedom to evolve through evidence.
Implementation then meets a 40-year-old AS/400 in a Leeds basement, undocumented COBOL, corrupted records and a 02:00 batch dump. The PowerPoint shatters. Teams build emergency wrappers while governance retreats into exception meetings.
Without shared constraints, squads build thirty microservices in four languages, six databases and bespoke authentication models, a distributed monolith joined by fragile queues. Each service looks healthy while the customer journey fails.
The parallel failure is the MOT Mentality. Security, GDPR and regulation are treated as a pre-launch inspection instead of design constraints. Audit arrives, finds exposed data and missing controls, and pulls the emergency cord, months and millions too late.
6. The Supplier on the Short Pier: Commercial Delivery Traps
Most enterprise trainwrecks feature a costly systems integrator holding the shovel. The trouble starts with the Vendor Bait-and-Switch. Veterans sell the outcome, then return to business development while a less experienced team arrives at premium rates.
Fixed price appears to transfer risk, but with uncertain scope and dependencies it rewards defence of the original specification. Learning becomes a Change Request. Delivery margin migrates into dispute.
As integration nears, immaculate burn-up charts meet code that will not talk to the legacy core, survive volume or reconcile data. The supplier cites client delays and ambiguous clauses, hands over two thousand pages of Confluence and strolls off the short pier, leaving the client with the burning wreckage.
Recognising that trajectory is only useful if leadership is prepared to intervene. Once the technical evidence, commercial incentives and supplier behaviour point in the same direction, the programme needs a controlled recovery response rather than another round of negotiation and revised status reporting.
7. The Programme Salvage Protocol: How to Recover Delivery Grip
When a programme lists and takes on water, management often adds the same things that caused paralysis, the emergency committees, daily spreadsheets and more governance. Recovery requires triage, operational discipline and the courage to remove dead weight.
This is the recovery protocol required to pull an enterprise back from the brink:
Step 1: The Commercial Emergency Brake
Stopping may be the cheapest intervention. Retest the business case, strategic need, technical premise and recoverable value. Cutting losses at £8m to protect £12m is an executive decision, not an operational failure.
Step 2: Enforce a Delivery Ceasefire
If the initiative still matters, freeze scope. No executive pet feature, stakeholder "must-have" or vendor change request enters until the baseline is stable. You cannot drain the swamp while someone pumps in sewage.
Step 3: Jettison the Ballast
Throw 70% of the backlog overboard, the administrative fluff, gold-plated edge cases and cosmetic preferences. Preserve the one capability the enterprise cannot operate without. Archive the rest.
Step 4: Build Hard Treaties Between Silos
Stop wasting time and money trying to bulldoze the silos. Instead, establish concrete technical treaties between the engineering grain towers and the compliance missile bunkers.
- Automate the Mandates: Encode security, GDPR and regulatory rules in the CI/CD pipeline. Violations break the build immediately. The bunker keeps its veto and engineering gets feedback without a three-week committee wait.
- Make Operations an Entry Gate: Logging, telemetry, tracing and automated rollback belong in the definition of done, not in a go-live handover.
Step 5: Deploy the Walking Skeleton
Do not attempt to rescue the entire application architecture at once. Construct and deploy a Walking Skeleton.
A walking skeleton is the thinnest end-to-end slice through live infrastructure. One real transaction crosses firewalls, authentication, services and the legacy core, then returns a verified result under live telemetry.
It exposes every bottleneck within weeks. If the skeleton cannot reach a shared environment through the deployment pipeline, the programme cannot ship. If it walks, add business logic on proven ground.
Step 6: Shift Quality Hard Left
Replace the six-week manual testing safety blanket with continuous quality from the first commit. Automate integration and performance checks and require deployable software every iteration. If release needs heroics, it is not complete.
8. The Delivery Reality Check: Act Before the Evidence Turns Red
Enterprise delivery is not agile theology. It is an engineering and commercial discipline for producing measurable, working value.
Failure is an accumulation of an unquestionable premise, unresolved dependencies, green reporting without integrated software, rising WIP, late operational involvement and suppliers defending contracts over outcomes. Several persistent signals mean the programme is already off course.
Boards can pay for truth early through a sharp reset, or pay many times over when dashboards turn red, suppliers retreat and the investment fails in public.
If your programme is burning money, hiding behind green dashboards or approaching a critical deadline without working software, contact Watchmen now. We will establish what is real, what is recoverable and what needs to stop, then restore the technical and operational grip needed to move forward.
Sources
Edward Yourdon, "Death-March Projects" (ICSE, 1997)
Judy E. Scott, "The FoxMeyer Drugs' Bankruptcy: Was it a Failure of ERP?"
UK Parliament Public Accounts Committee, "The dismantled National Programme for IT in the NHS"